

Over the last few months, I have been quietly building something I call Marie’s Brain - a private AI co-pilot grounded in my hand-curated Open Knowledge Format (OKF) library of Search and AI research, paired with a client’s actual site context and $500 Diagnostic Report.
Recently, I switched the tool over to Google’s new Gemini 4 Hydrogen model. After using it for a while, though, I had a nagging feeling: is Hydrogen actually producing better answers than Gemini 3.8 Flash, or am I just assuming newer means better?
Instead of guessing, I decided to run a real blind taste test - and threw Gemini 4 Neon into the mix too.
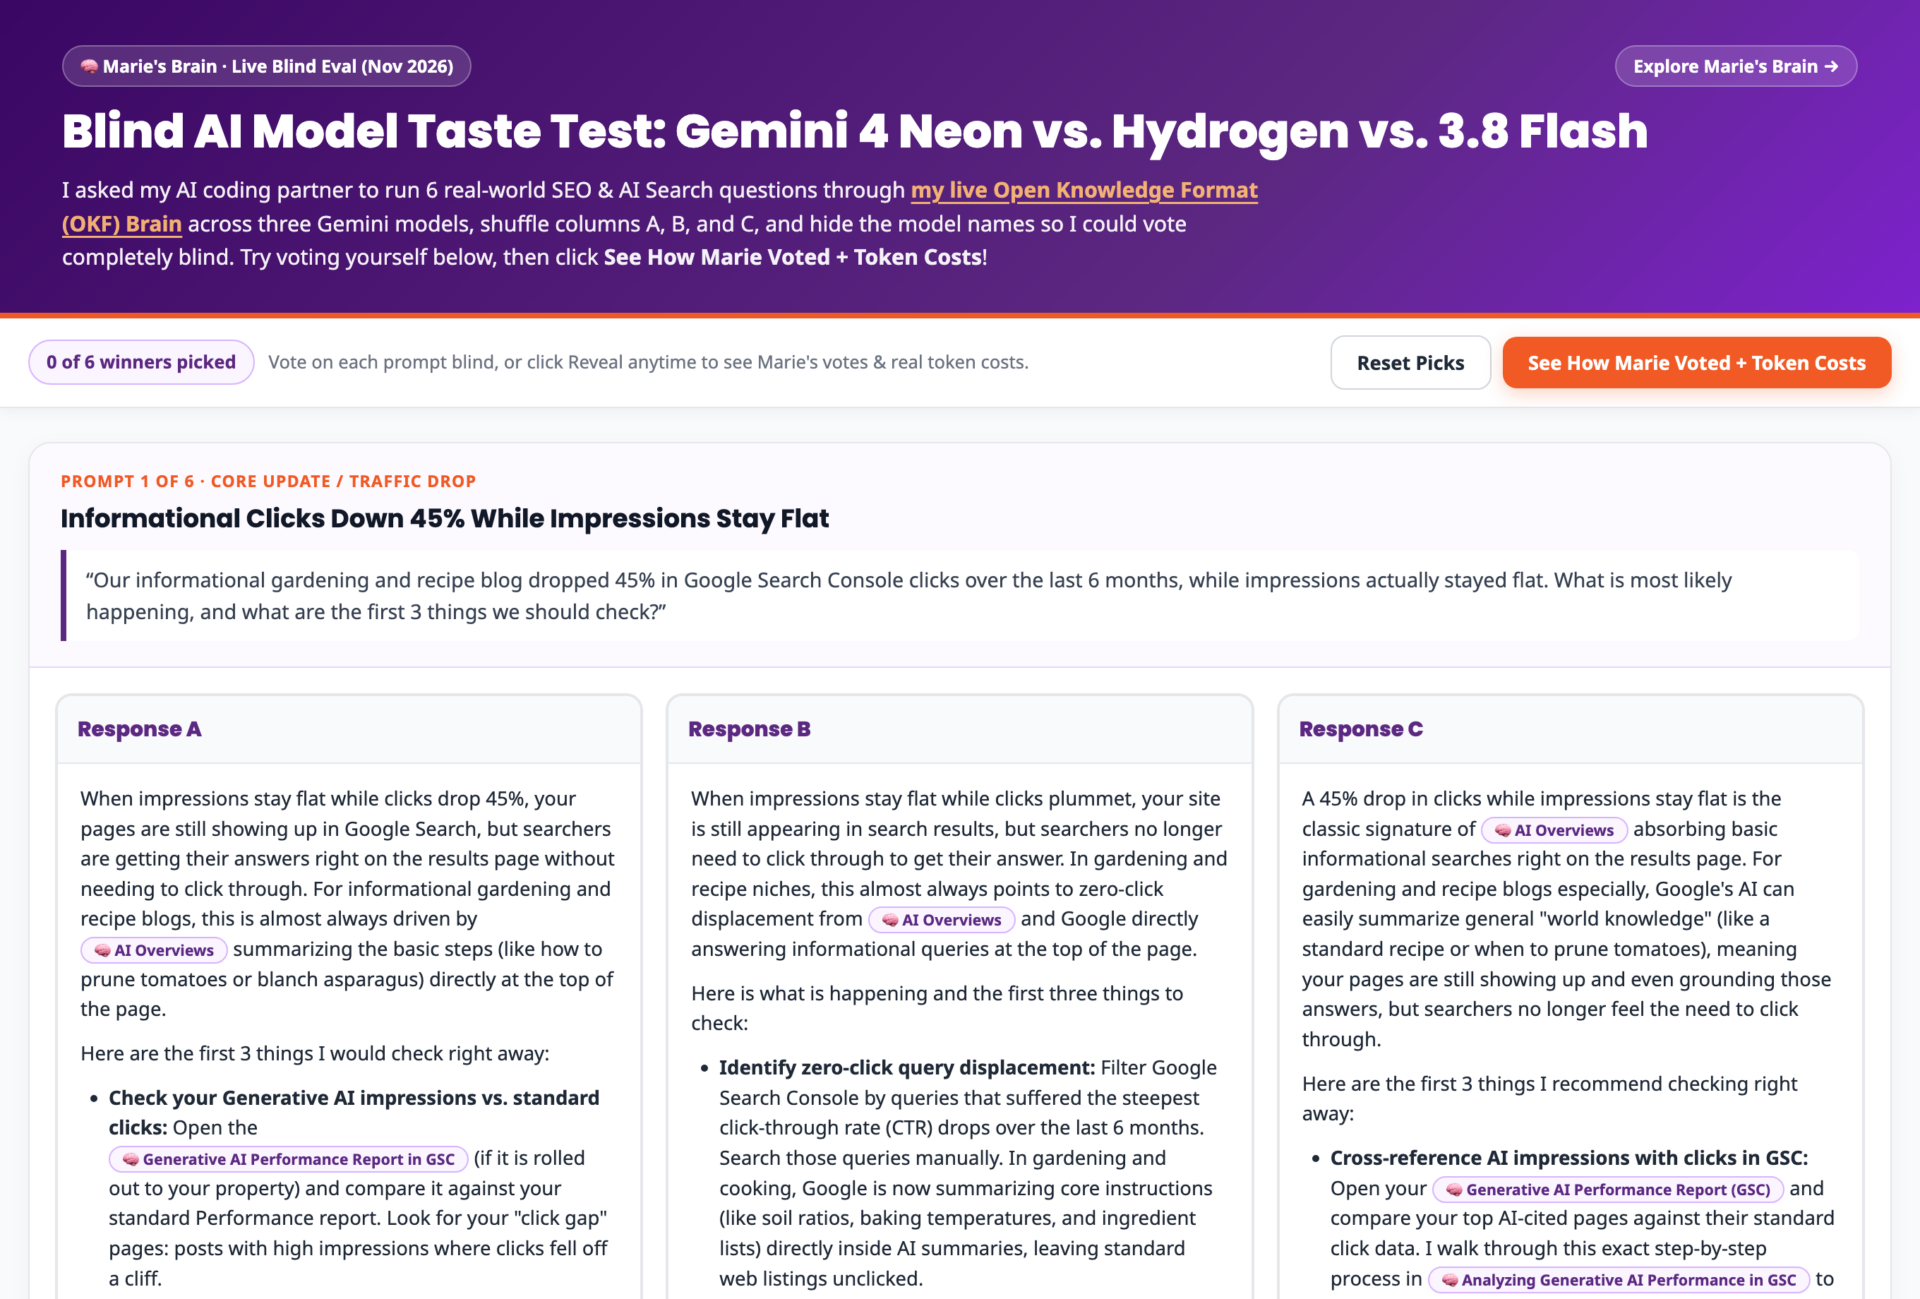
You can actually try the exact same 6-question blind test yourself here (columns A, B, and C are shuffled on every question, and there is a button at the top to reveal how I voted and the real token costs).
Surprise #1: Our First Test Exposed a Prompt Problem
Before I even finished reading the first round of blind outputs, one thing jumped out immediately: the answers were way too long.
My Brain had been defaulting to Detailed mode with no word ceiling. When we checked the API logs, we discovered something wild: Gemini 4 Hydrogen was going into an over-eager research loop, reading an average of 21 OKF files per question, taking 68 seconds, writing 1,600-word essays, and costing $0.44 per prompt - actually more expensive per turn than Gemini 4 Neon!
On top of that, some answers were dropping internal Google engineering jargon (like MAGIT and FastSearch) that a busy business owner does not need to wade through just to figure out why their clicks dropped.
So before doing my real blind vote, I made three quick upgrades to how Marie’s Brain works:
- Switched the default to Concise mode (~180 - 280 words) so answers read like a quick, practical call with me (users can still toggle Detailed anytime).
- Capped tool lookups to 1-2 targeted OKF files per turn so the model stays fast and focused.
- Banned internal Google patent codenames unless someone specifically asks how Google’s internal systems work.
Then we re-ran the exact same 6 real-world SEO and AI Search questions - covering AI Overviews and traffic drops, whether to delete or rewrite informational posts, Main Content on commercial buyer’s guides, pruning thin location pages, agent readiness and /llms.txt, and a realistic 5-hour-a-week plan that skips GEO distractions - across Gemini 3.8 Flash, Gemini 4 Hydrogen, and Gemini 4 Neon.
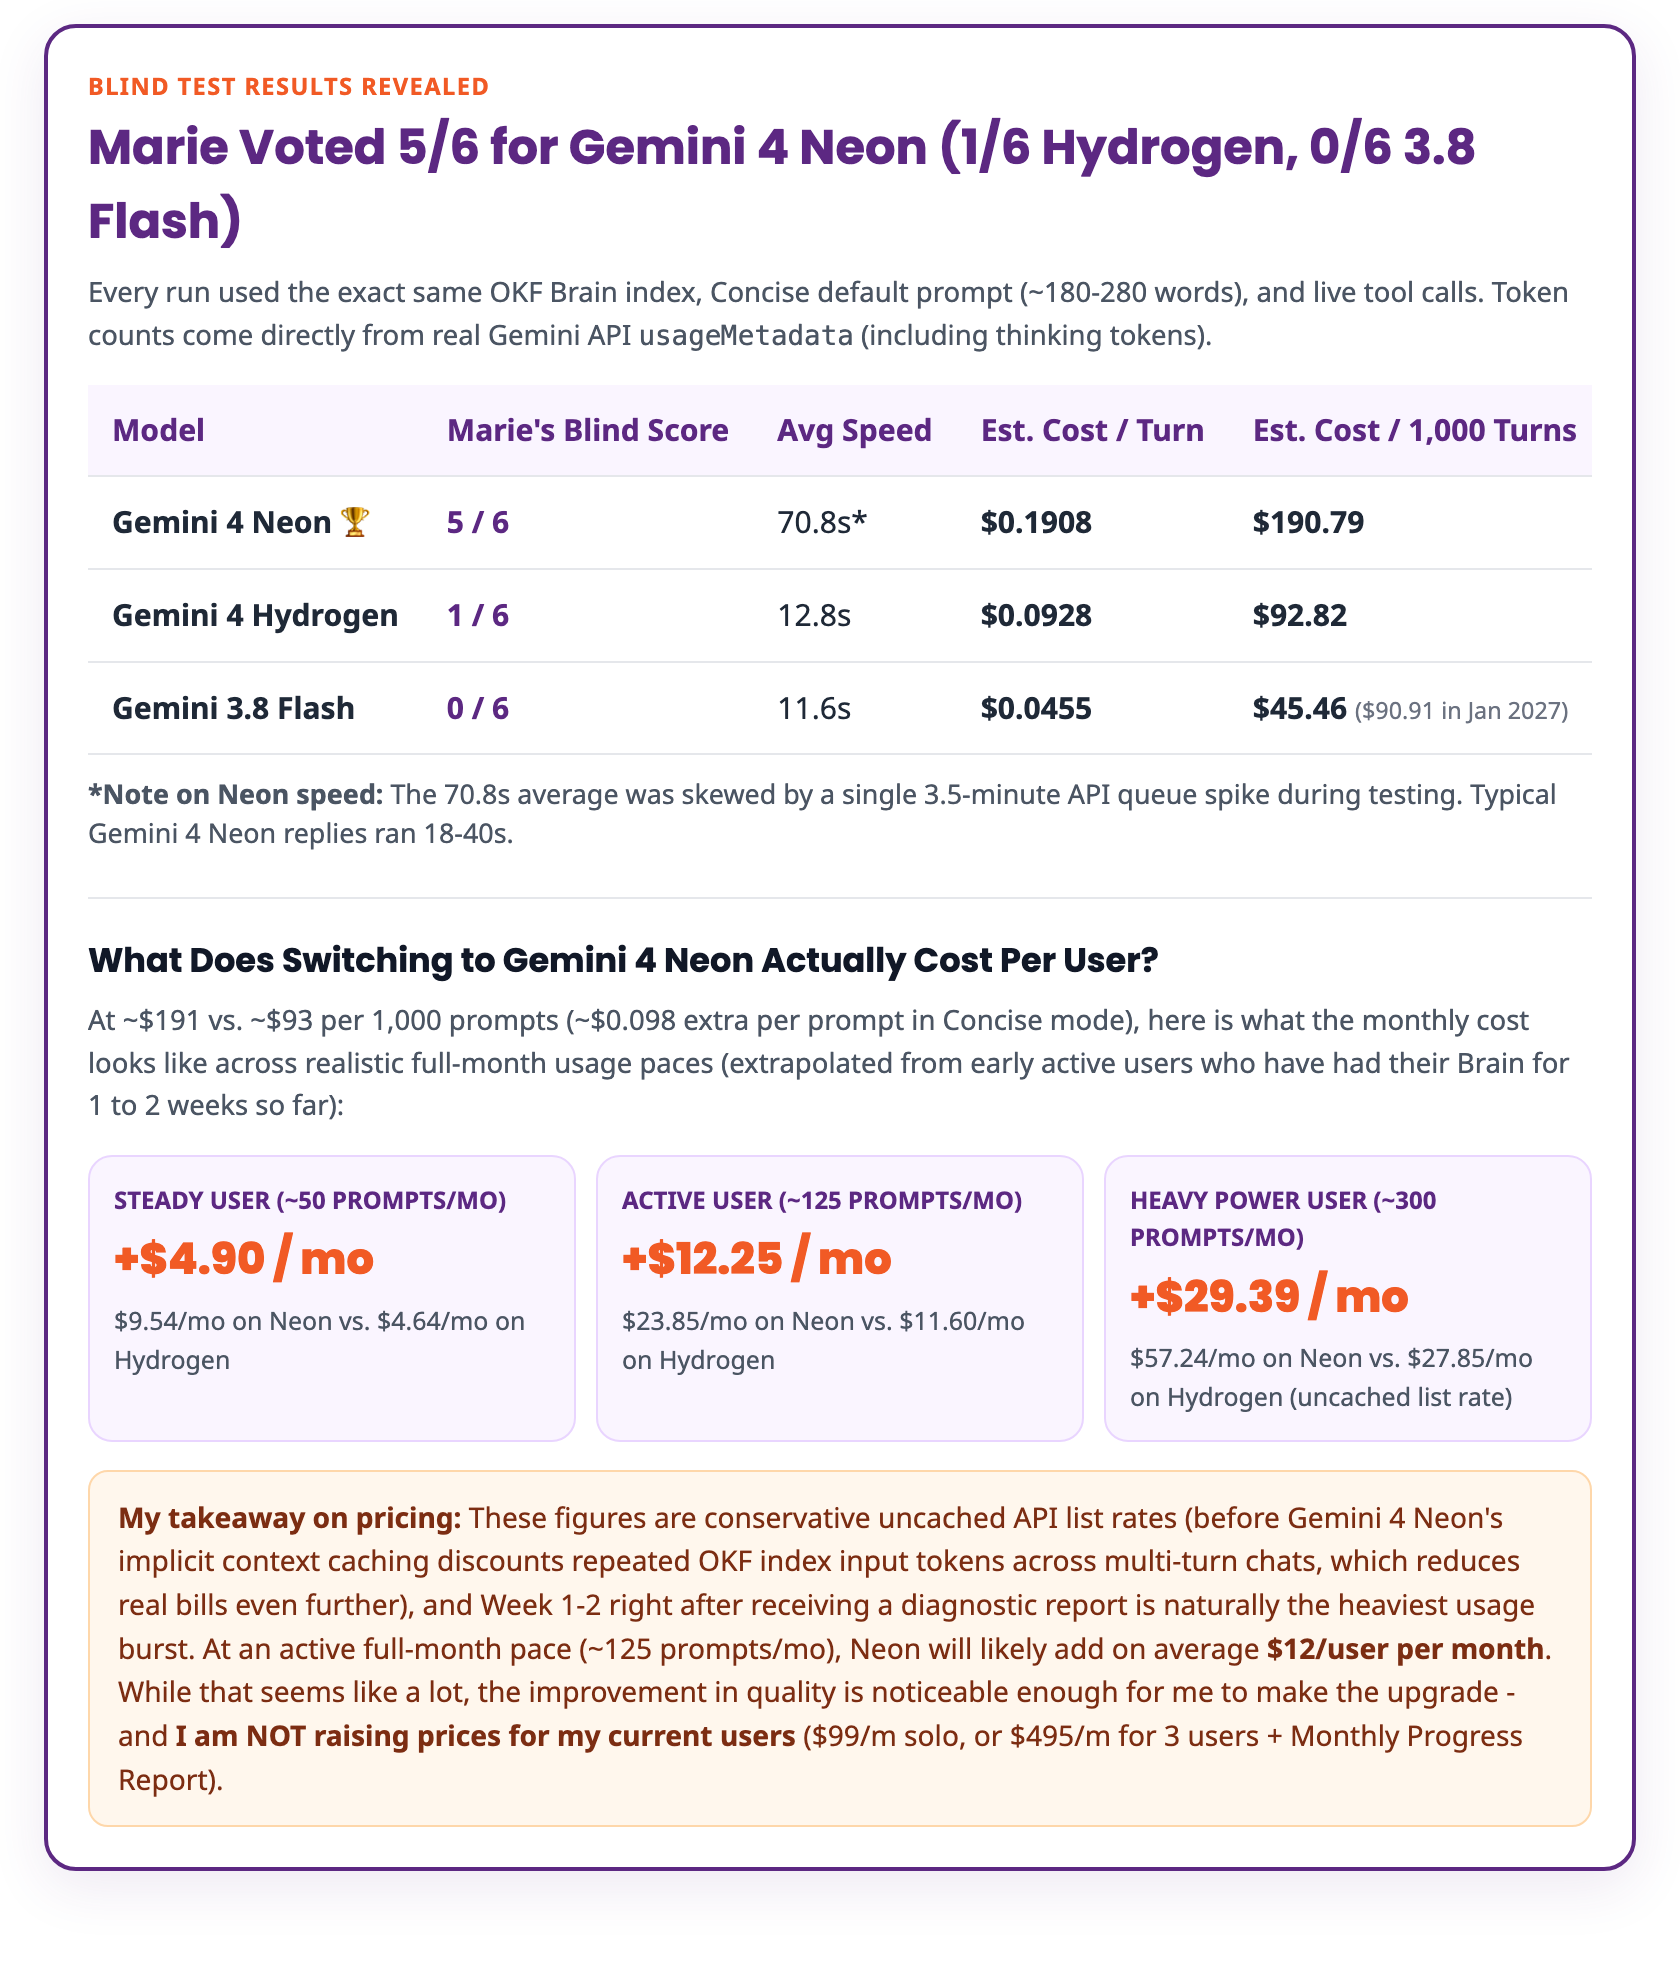
My Blind Result: 5 out of 6 for Gemini 4 Neon
With the model names hidden and the columns randomized, I read all 18 answers and picked a winner on every prompt.
When I hit reveal, the result wasn’t even close:
- Gemini 4 Neon: 5 / 6
- Gemini 4 Hydrogen: 1 / 6
- Gemini 3.8 Flash: 0 / 6
What stood out to me about Neon wasn’t that it had more facts - all three models pulled from the exact same OKF files. It was how it communicated. Neon’s answers felt more like a smart human thinking through a problem rather than a predictable AI response. I genuinely enjoyed reading them, and I immediately understood what they were trying to get across.
What Does Gemini 4 Neon Actually Cost?
Of course, better answers only matter if the economics make sense. Here are the real numbers from our live Concise-mode runs (using real Gemini API usageMetadata, including thinking tokens, at conservative uncached list rates):
| Model | Avg Speed | Avg Length | Est. Cost / Turn | Est. Cost / 1,000 Turns |
|---|---|---|---|---|
| Gemini 3.8 Flash | 11.6s | 292 words | $0.0455 | $45.46 (~$91 in Jan 2027) |
| Gemini 4 Hydrogen | 12.8s | 239 words | $0.0928 | $92.82 |
| Gemini 4 Neon (5/6 Winner) | 70.8s | 275 words | $0.1908 | $190.79 |
Note on Neon’s speed: That 70.8s average was skewed by one single 3.5-minute API queue spike during testing; typical Neon replies ran 18 to 40 seconds (with text streaming on screen as it writes).
At first glance, $191 vs. $93 per 1,000 prompts sounds like a big jump (about 10 cents extra per prompt). But when I mapped that against realistic full-month usage paces extrapolated from my early active users, here is what the extra cost per user looks like:
- Steady user (~50 prompts/month): +$4.90/month extra for Neon ($9.54 vs. $4.64)
- Active user (~125 prompts/month): +$12.25/month extra for Neon ($23.85 vs. $11.60)
- Heavy power user (~300 prompts/month): +$29.39/month extra for Neon ($57.24 vs. $27.85 uncached)
And those are conservative uncached estimates. Because every turn references the same ~55K-token OKF Master Index, Gemini 4 Neon’s implicit context caching discounts repeated input tokens across multi-turn chats, bringing real-world bills noticeably lower.
At an active full-month pace (~125 prompts/month), Neon will likely add on average $12/user per month. While that seems like a lot, the improvement in quality is noticeable enough for me to make the upgrade - so I upgraded Marie’s Brain to default to Gemini 4 Neon for everyone without raising prices (while keeping Hydrogen and 3.8 Flash available in the model picker if someone wants an instant reply).
Want to Try It Yourself (or Use Marie’s Brain on Your Site)?
If you want to see the difference for yourself, take two minutes to vote blind on the 6 SEO questions here: Blind AI Model Taste Test: Neon vs. Hydrogen vs. 3.8 Flash. (Try clicking any of the purple concept pills inside the answers too - inside Marie’s Brain, those open my full hand-curated documentation on each topic.)
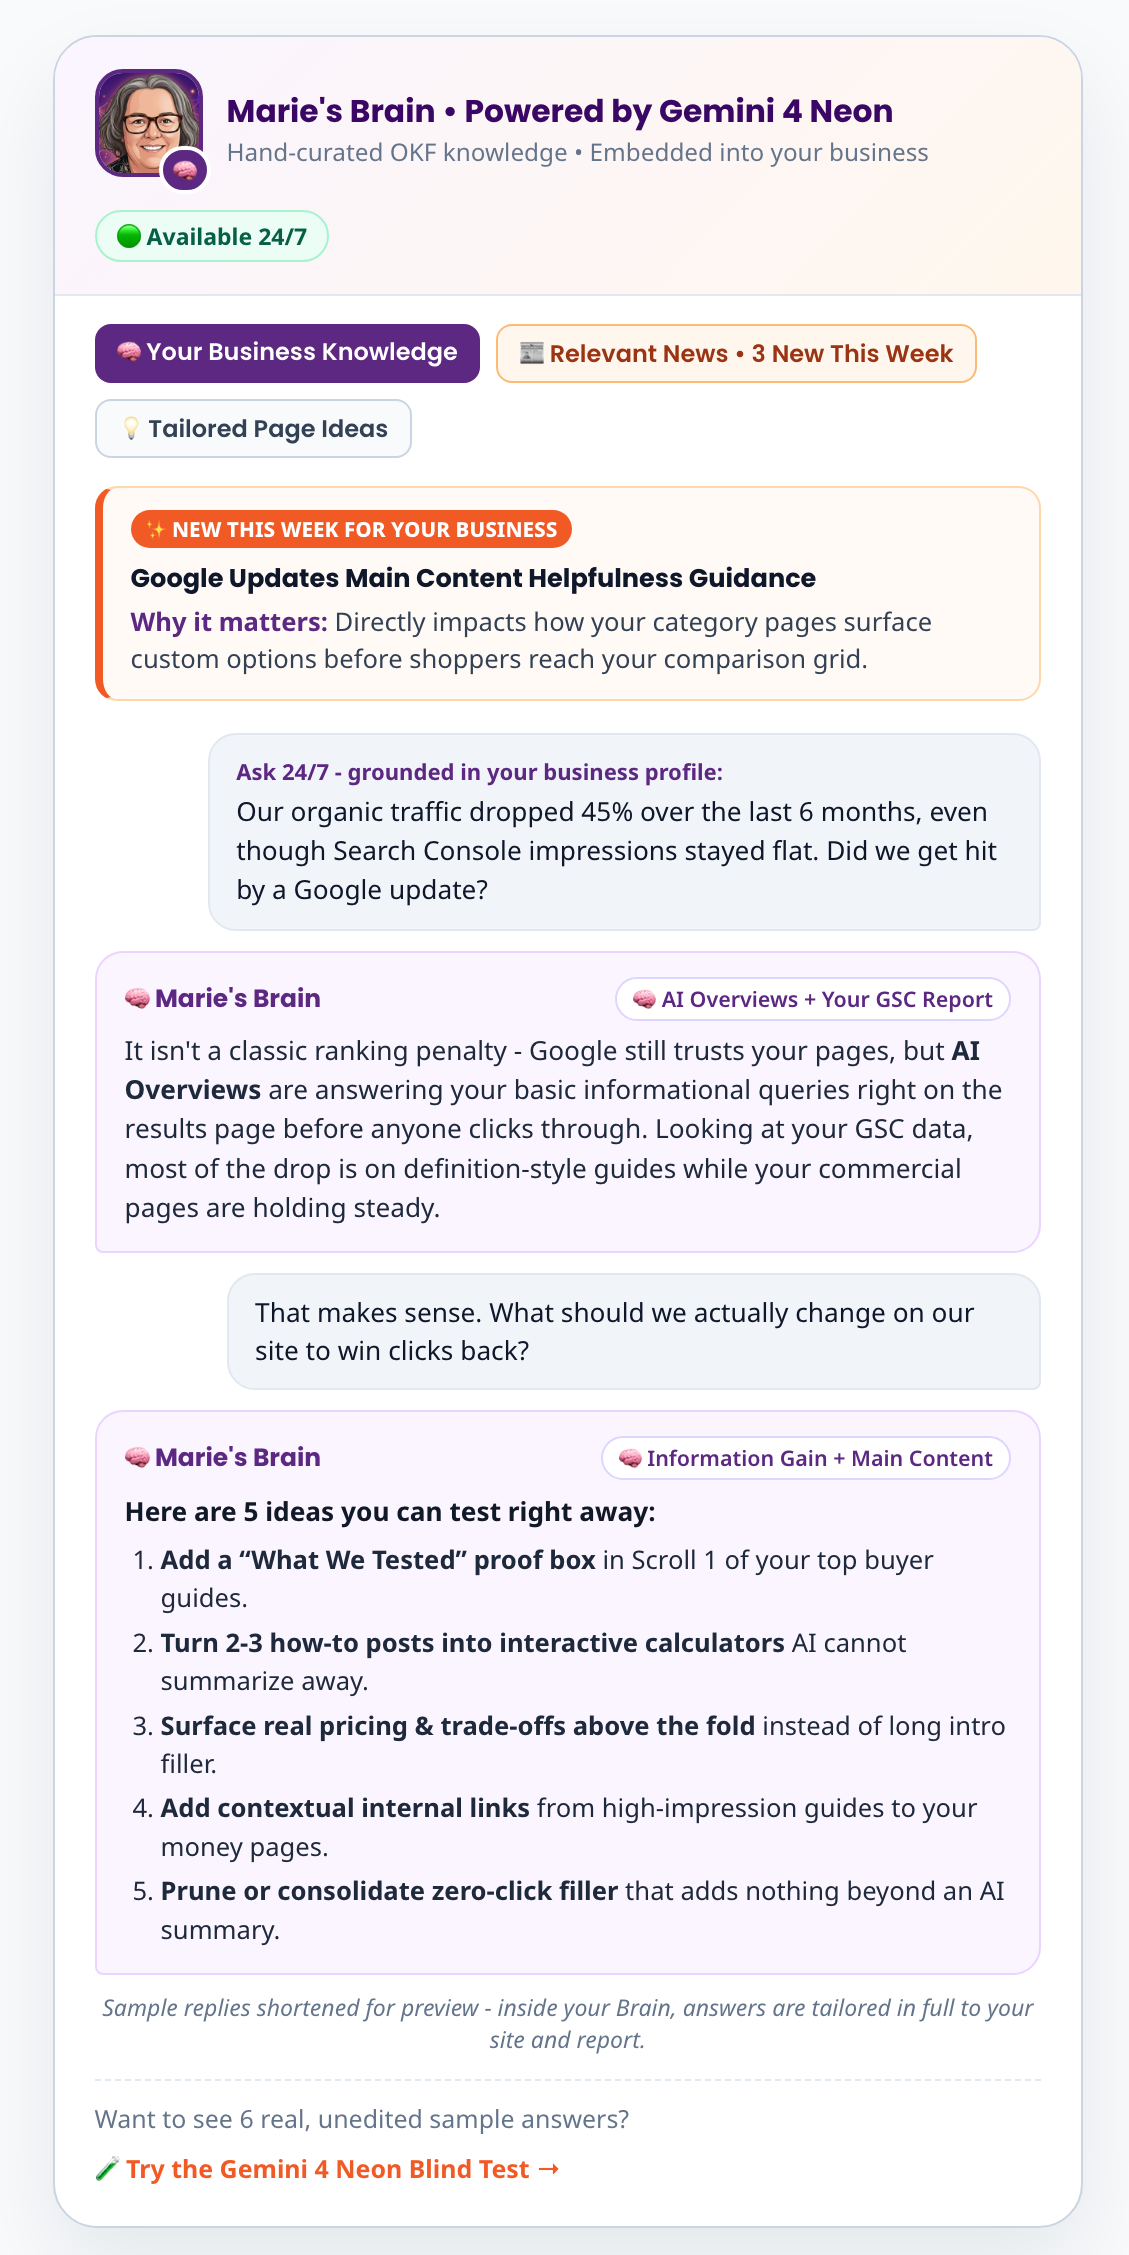
I am not opening standalone public signups for Marie’s Brain just yet, but right now 30 days of complimentary early access - pre-loaded with your website profile and full Search Console and GA4 analysis - is included with every $500 Diagnostic Report. You can also preview how it works and join the public waitlist anytime at brain.mariehaynes.com.
Early Access Included
Want Marie’s Brain (Powered by Gemini 4 Neon) Pre-Loaded With Your Site?
Every $500 Diagnostic Report includes a deep-dive analysis of your Google Search Console data, traffic trends, and AI Search visibility - plus 30 days of complimentary early access to Marie’s Brain pre-loaded with your business profile and full report.
If you liked this, you’ll love my newsletter:
Or, join me in the Search Bar for up-to-the-minute news on Search and AI.
Comments are closed.